High-performance GPU infrastructure for AI, machine learning and data-intensive workloads.
Nepal’s Own AI Cloud
Nepal’s first sovereign AI cloud — access powerful NVIDIA GPUs hosted right here in Kathmandu. Train models, deploy LLMs, run inference, and accelerate research without expensive hardware imports or foreign cloud latency. Built for Nepali businesses, researchers, and developers.

The latest NVIDIA GPUs for AI training, inference, data science, simulation, rendering and high-performance computing.

No large capital investment. Scale GPU resources up or down to match your workload.

Launch GPU instances, virtual machines, containers and AI environments within minutes.

Pay with eSewa, Khalti, bank transfer or corporate invoice. No USD, no foreign currency account and no NRB approval needed.

Every GPU node is in a Kathmandu data center, which matters for banks, insurance, healthcare and other regulated industries.

Isolated multi-tenant workloads, continuous monitoring and SLA-backed availability.

Pre-configured environments for LLMs, generative AI, machine learning, deep learning, computer vision, data science, AI agents and MLOps.
The hardware
The same GPUs used by the world’s leading AI labs, now available in Nepal.

Hopper · 80 GB HBM2e · 2 TB/s. Ideal for LLM fine-tuning and enterprise AI training.

Blackwell · 96 GB GDDR7 · ~1.8 TB/s. Ideal for large-model inference and rendering.

Ada Lovelace · 24 GB GDDR6 · 300 GB/s. Ideal for cost-efficient inference serving and light training.

Hopper · 141 GB HBM3e · 4.8 TB/s. Built for large-scale training.

Ada Lovelace · 48 GB GDDR6 · 864 GB/s. A universal GPU for training and inference.
Two ways to start
A managed AI experimentation environment for students, researchers, university labs, bootcamps and enterprise upskilling. GPU access, pre-built Jupyter notebooks, collaborative workspaces and GPU monitoring dashboards. No infrastructure knowledge required.
On-demand GPU virtual machines on H100, RTX PRO 6000 Blackwell and L4 for ML engineers, AI startups, enterprise teams and production inference APIs. CUDA, PyTorch, TensorFlow, vLLM, DeepSpeed and Jupyter pre-installed, with full root access.
How it works
Call, WhatsApp or use the contact form. Tell us about your workload and we will recommend the right GPU and configuration.
Receive a ready environment with CUDA, PyTorch, TensorFlow, Jupyter and vLLM installed. No setup required.
Experiment in AI Lab, train on H100 or RTX PRO 6000 Blackwell in GPU Workspace and serve low-latency inference APIs.
Move to reserved instances or Bare Metal for production, with 24/7 monitoring by our team in Kathmandu.
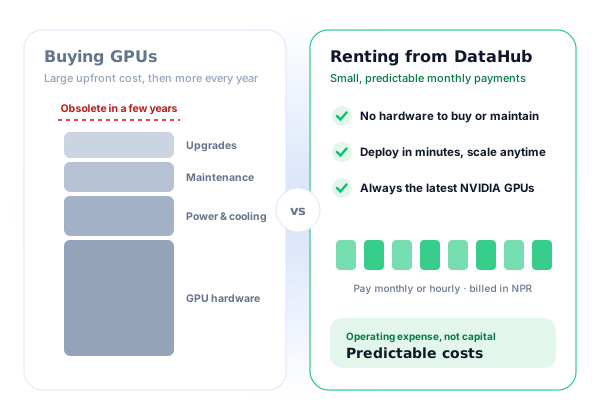
Rent vs buy
Buying enterprise GPUs means a large upfront investment plus ongoing maintenance, cooling, power and infrastructure management. With DataHub GPU Cloud you get:
Talk to our team about your training, inference or research workload, or visit YetiCloud.AI to learn more.